About of Transformers In Nlp Explained Self Attention Encoder Decoder Positional Encoding
Looking for the latest information on Transformers In Nlp Explained Self Attention Encoder Decoder Positional Encoding? We've researched comprehensive data, records, and insights about Transformers In Nlp Explained Self Attention Encoder Decoder Positional Encoding.
Core Information
Explore the main sources for Transformers In Nlp Explained Self Attention Encoder Decoder Positional Encoding.
Latest News
Stay updated on Transformers In Nlp Explained Self Attention Encoder Decoder Positional Encoding's latest milestones.
Illustrated Guide to Transformers Neural Network: A step by step explanation
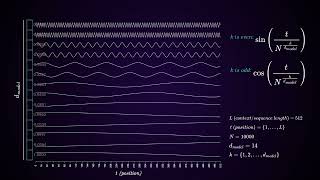
How positional encoding works in transformers
Transformers in NLP Explained | Self-Attention, Encoder-Decoder & Positional Encoding
Positional Encoding in Transformer Neural Networks Explained
Transformers Explained | Simple Explanation of Transformers
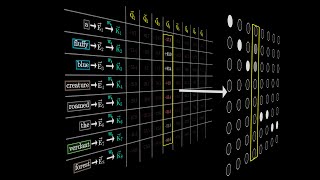
I Visualised Attention in Transformers
Transformer models: Encoder-Decoders
Transformers, the tech behind LLMs | Deep Learning Chapter 5
Transformers and Self-Attention (DL 19)
How Attention Mechanism Works in Transformer Architecture
Transformers, explained: Understand the model behind GPT, BERT, and T5
Detailed Analysis
Data is compiled from public records and verified media reports.
Last Updated: September 14, 2026
Final Thoughts
For 2026, Transformers In Nlp Explained Self Attention Encoder Decoder Positional Encoding remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.